

Resources
Blogs
Best open-source tools for LLM evaluation and prompt management (2026)
Roundup of open-source and popular tools for LLM evaluation and prompt management: OpenLIT Prompt Hub and evaluations, Langfuse, Arize Phoenix, Comet Opik, Braintrust, and Promptfoo, and where each fits.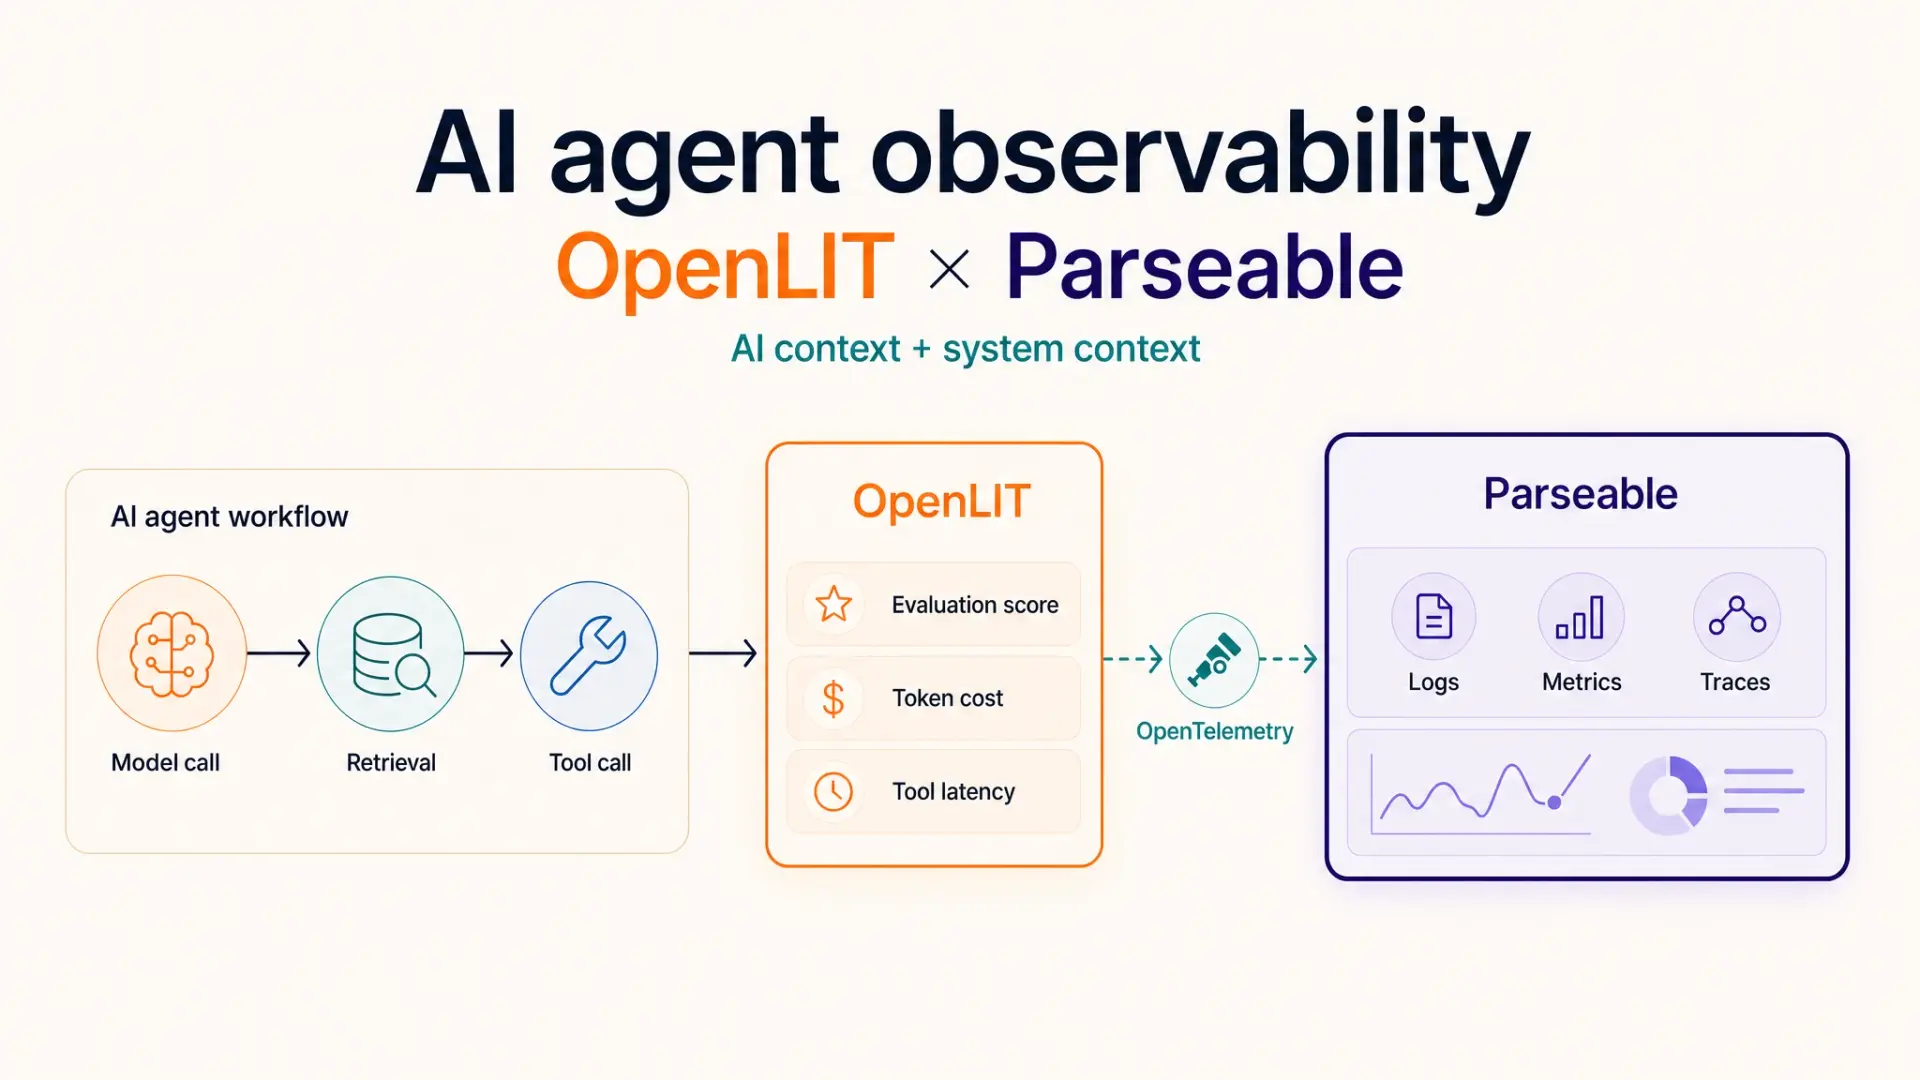
AI agent observability with OpenLIT and Parseable
Build AI agent observability with OpenLIT and Parseable to trace model and tool calls, evaluate output, retain telemetry and investigate incidents.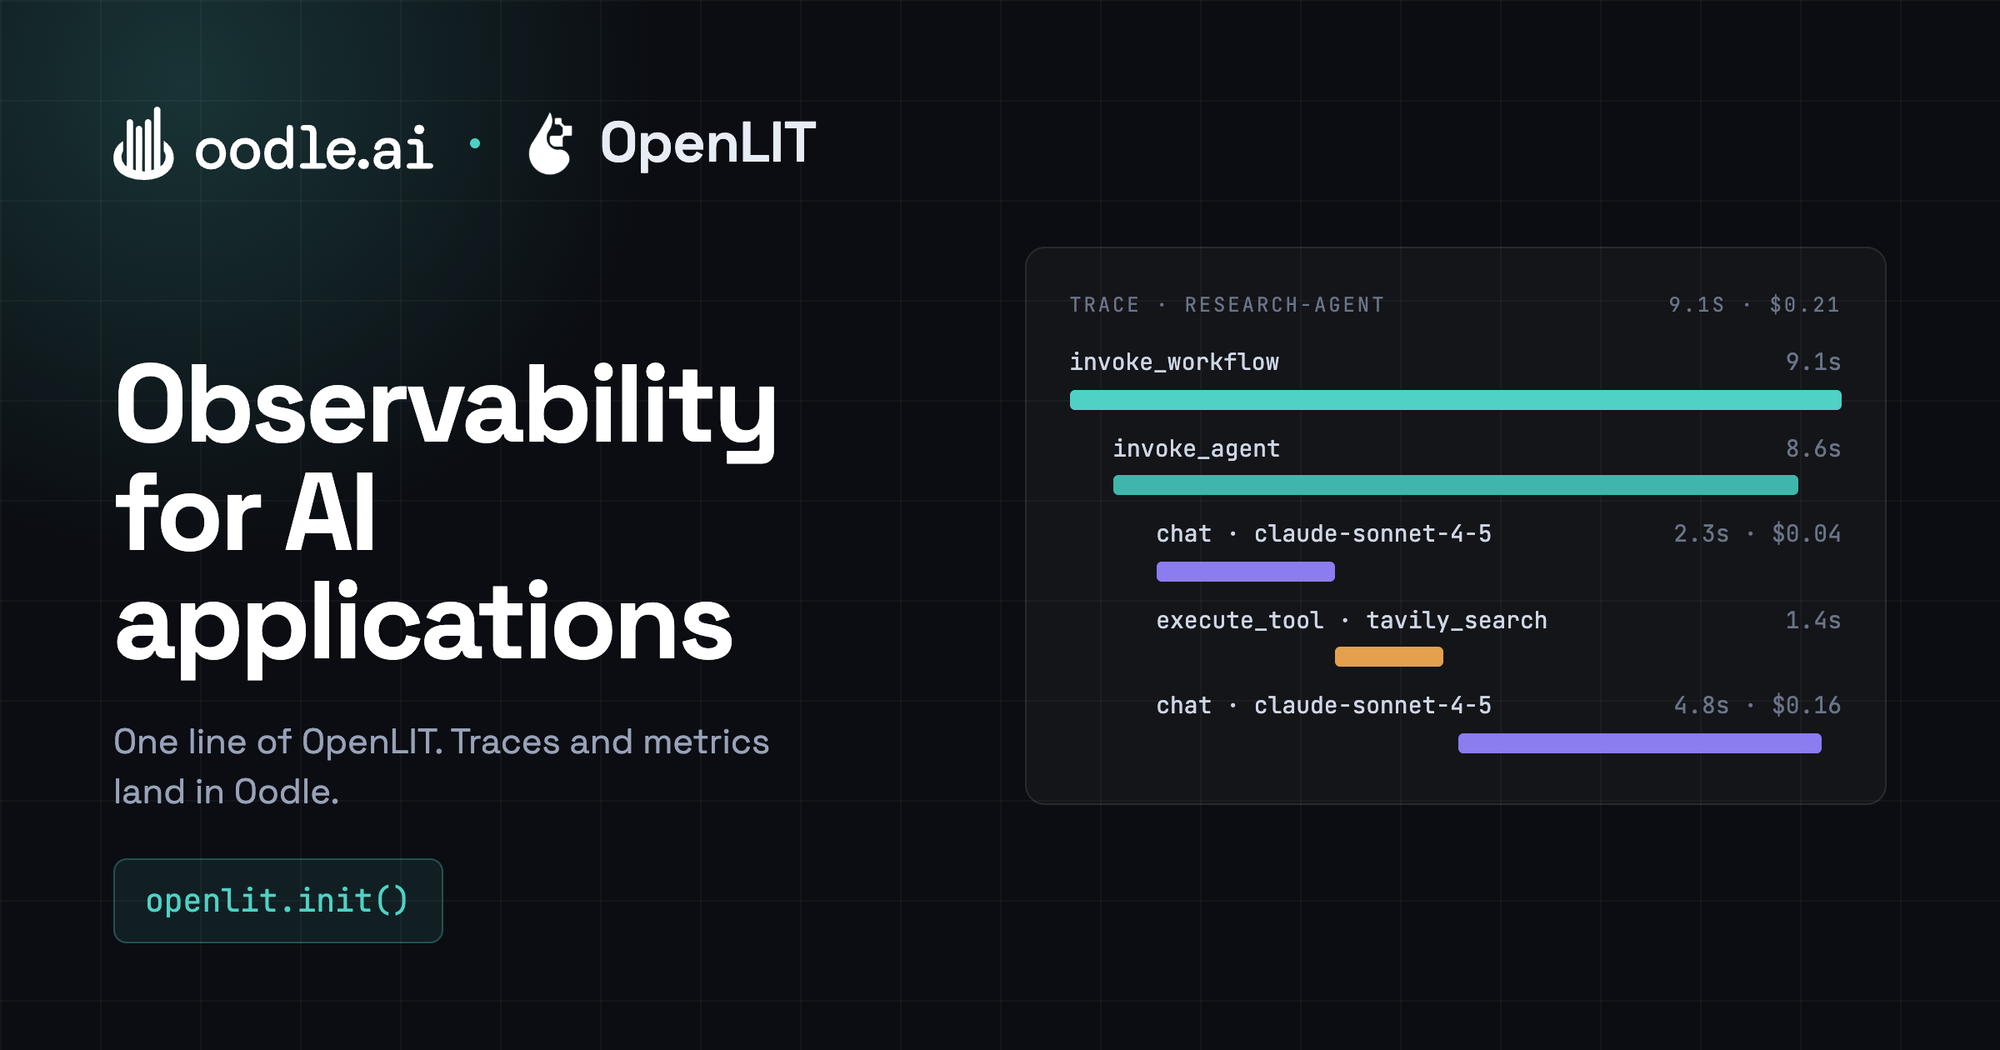
Observability for AI Applications Using Oodle and OpenLIT
Instrument LLM apps and agents with OpenLIT in one line and ship both metrics and traces to Oodle.
GPU Utilization Is a Vanity Metric. Here is the GPU SLI for Inference
GPU utilization from nvidia-smi, DCGM, and NVML is a vanity metric for LLM inference. SLO memory headroom, throttle-free time, allocated vs idle, CUDA health, and NVLink instead. OpenTelemetry hw.gpu metrics work with OpenLIT or any OTLP backend.
Talk to Your Telemetry: Debugging LLMs with OpenLIT's Otter AI Copilot
A deep dive into OpenLIT's Otter AI Copilot—the tool-calling assistant that lets you query traces, write Rule Engine rules, manage the Prompt Hub, and register custom model pricing conversationally.
Observability for LLM Apps and Agents: OpenLIT SDK + VictoriaMetrics Observability Stack
A joint OpenLIT + VictoriaMetrics guide to observability for LLM apps and agents - OTel GenAI semantic conventions, PromQL queries for cost, recursion, and cache hit rate, alerting rules that earn their keep, and a fully self-hosted, vendor-neutral pipeline for metrics, traces, and logs.
How to Detect Hallucinations in Your RAG Pipeline (with Code Examples)
Catch LLM hallucinations programmatically using OpenLIT's evaluation SDK. Includes Python code examples for hallucination, toxicity, and bias detection with OpenTelemetry export.
Tracking LLM Costs in Production: Per-Model, Per-Request, Per-User Attribution
Break down LLM costs by model, service, user, and environment using OpenLIT. Auto-calculated token costs exported as OpenTelemetry metrics to Grafana, Datadog, or any backend.
GPU Monitoring for LLM Inference: What to Track and Why It Matters
Learn which GPU metrics matter for LLM inference workloads and how to collect them as OpenTelemetry signals using OpenLIT's GPU collector. Supports NVIDIA and AMD.
How to Add Observability to Your LLM App in 2 Minutes with OpenTelemetry
Add full tracing, metrics, and cost tracking to any LLM application with one line of code using OpenLIT and OpenTelemetry. Works with OpenAI, Anthropic, and 40+ providers.
Fleet Hub Playbook for Multi-Region AI Observability
Coordinate fleets of OpenTelemetry collectors for GenAI workloads with OpenLIT Fleet Hub and the OpAMP protocol.
Monitoring LLM Usage in OpenWebUI with OpenLIT
This guide walks you through integrating OpenLIT with OpenWebUI using pipelines, covering installation, configuration, and practical use cases for monitoring and observability of LLMs including token tracking, cost analysis, and GPU metrics.
How to protect your OpenAI/LLM Apps from Prompt Injection Attacks
Learn how to safeguard your OpenAI and LLM apps from prompt injection attacks using UUIDs, input validation, and monitoring strategies with OpenLIT.
Unlocking Seamless GenAI & LLM Observability with OpenLIT
OpenLIT offers seamless, OpenTelemetry-native observability for GenAI and LLMs, simplifying performance and cost tracking.